Case study · Public agentic system
A civic data reference built in a day, and kept current by agents
Built inside a day from a paragraph of intent, then kept current by six pull-request-only agents behind a human merge gate. Every published fact carries its source, the date it was checked, and who verified it.
What it is
coloradofirearmswatch.org is a sourced public reference for Colorado’s Specified Semiautomatic Firearms law. It answers three narrow questions for a person who has to make a decision: is a specific model on the state’s covered list, what changed between one version of that list and the next, and what is my county actually doing about eligibility cards. It carries a litigation tracker alongside. It is a reference in a field-manual tone, and it is not legal advice.
The build is what earns it a place in this portfolio. An AI agent stood the whole thing up end to end in about a day, and it stays correct through a monitoring pipeline that stops on anomaly and waits for a human. Same governance thesis as the rest of this site, at the speed end of the spectrum.
The build emits on the order of 1,165 pages: a dedicated page for each of the 858 covered models and each of the 64 counties, plus the list-version diffs, the case pages, the training listings, and the reference material. Every one is generated from the versioned data and re-rendered on each merge, and none is maintained by hand. What got automated here is the whole civic-data reference process, ingestion through publication, kept running by agents behind a human merge gate.
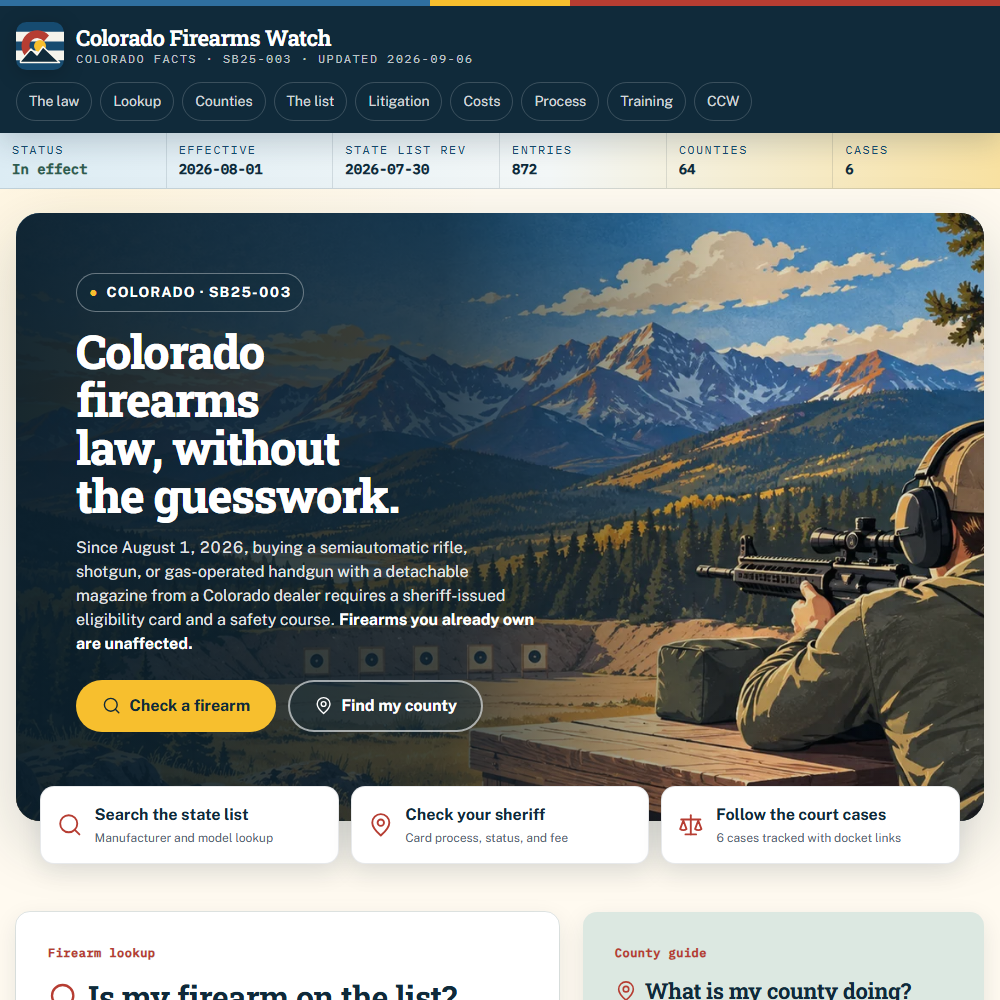
The build: a day, from a paragraph
I gave the agent a paragraph of intent that I had sketched on a long drive: a sourced reference for the statute, field-manual tone, no advocacy. From that, the agent scaffolded the Astro site, wrote the Python agents that scrape the official sources, wired the continuous-integration workflows, and deployed to production. The first commit is timestamped the evening of July 8, 2026, and the site was live within roughly a day. I scoped the concept and the guardrails, and I hold the merge. I did not write the application code.
The commit history and the live site are what I can stand behind. The moment of “concept” happened on a drive and is not in git, so the under-a-day figure rests on my account plus the first-commit timestamp. This is the third public site I have had built this way, after walletrecovery.info and cheatsheets.davidveksler.com.
The data pipeline: monitor, diff, and open a pull request
A reference is only worth anything if it stays current, and a state firearms list is a moving target: it gets revised, counties change posture, cases advance. So the site is kept current by six scheduled agents, each pointed at an official source. One parses the state’s covered-model list from the source PDF. Others watch that list for diffs, recheck county status, watch a Colorado Parks and Wildlife feed, and poll active litigation through the CourtListener API. A last one dispatches alerts. They run on a cadence from daily to every six hours.
The governance is in what those agents are not allowed to do. No agent can push to the main branch. Each one parses its source, diffs the result against the committed data, and opens a pull request. A human merges, and the merge is what triggers the rebuild and the alerts. It is the same merge-gate invariant as the regulated-lender and cheatsheets work, applied to civic data.
A bad scrape stops before it becomes a bad fact
Scrapers break quietly. A source site changes its markup, a PDF layout shifts, and a naive pipeline commits garbage with full confidence. This one is built to fail loudly. If an agent sees a parse deviation, an entry-count swing beyond twenty percent, or an extraction error, it skips the data pull request entirely. It opens an issue, sends a push notification, and exits nonzero, and the suspect artifact is attached to the run for a person to look at. The default on anomaly is to stop and surface. A twenty-percent swing in the size of a firearms list is either real news or a broken scraper, and either way a human should look before it ships.
The loop runs both ways
The six monitors are the outbound half: watch official sources, diff, open a pull request. The inbound half is automated too. Public input, a correction to a model entry, a report of what compliance cost someone, a training course to list, arrives through a form backed by a Cloudflare Worker that turns each submission into a labeled GitHub issue, with a honeypot field, rate limiting, and CORS in front of it. Three of those forms are live. A stranger’s correction becomes a labeled issue, then a candidate pull request, routed to the same human merge gate as everything else, and nobody sorts an inbox by hand. On the way out, every merged data change dispatches its alert emails automatically, and scheduled routines draft outreach for a human to review and send.
So the human is left holding two decisions, the merge and the send. Parsing sources, diffing versions, triaging what the public submits, drafting the alerts and the outreach, rendering a thousand pages: all of that is agent work. A reference like this would normally be somebody’s part-time job, and what the pipeline absorbed is the clerical volume that made it one.
Provenance sits on the page
Every published data point carries three things: the source URL it came from, the date it was last checked, and a verification tier, whether a human, an agent, the community, or no one yet has confirmed it. Those render as a chip on the page, so a visitor sees the provenance of a claim next to the claim. The data layer itself is versioned JSON in git, read only at build time, and corrections arrive as tracked changes through an intake form. Nothing edits a live database. Raw source PDFs are kept and hashed so a figure can be traced back to the exact document it was read from.
This is the same rule the investor-enrichment service runs on, that no unsourced claim ships, pointed at a different problem. There, the reader was an internal rep who had to trust a draft. Here, the reader is a stranger deciding something that matters to them, so the proof has to sit on the page itself.
Limits
This is a personal-scale civic project and the numbers are smaller for it. It differs from the cheatsheets project in one important way: that repository and its full history are public, and this one is not. You can check the output, the live site with its provenance chips, source links, and dates, the page for each model and each county, and the three public intake forms. You cannot check the pipeline behind it. The commit count, the changelog deltas, the agent cadence, the Worker and outreach routines, and the roughly 1,165-page build total on this page are verified against a private repository and reported on my word; the model, county, and case counts, and the intake forms themselves, are on the live site, where you can check them yourself.
Where it fits
The Antech and regulated-lender case studies show agentic engineering carrying load inside companies, where the strongest numbers are internal. The cheatsheets project shows a governed content pipeline that is public end to end. This one sits next to cheatsheets as the other public, one-person system, and it makes a different point. Cheatsheets is a spec-driven library accreting over a year. This is a full production system, data pipeline and monitoring included, stood up in a day and then kept current by agents that stop on anomaly and wait behind a merge gate. Speed and governance usually trade against each other. Here the merge gate is what made the speed safe to keep.
coloradofirearmswatch.org, the live reference ↗ Email me about this Where I fit best ← All case studies